PlantAI
Photograph a houseplant, get a diagnosis, then find the fix in a real nursery
- 1,279
- automated tests, run on every push
- 60
- pull requests merged into main
- 5
- external providers, all behind one gated API
9 minutes, screen recorded - Google Drive
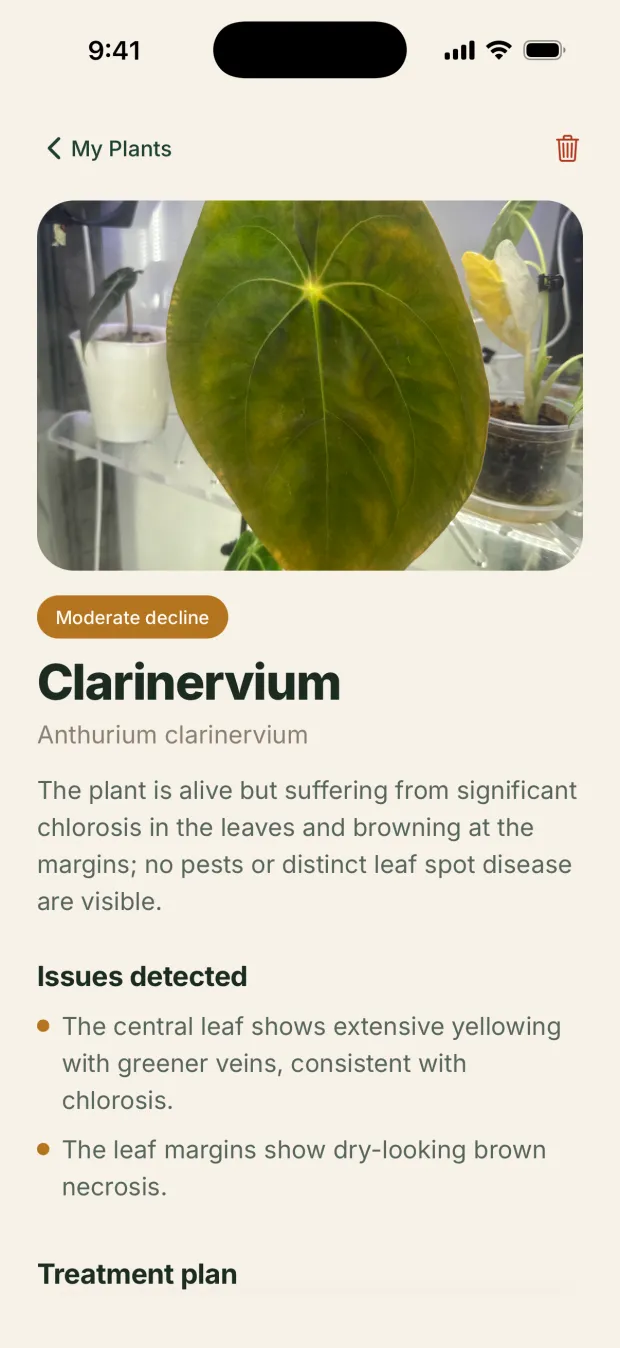
Diagnose
What it is, how it is doing, and what it found wrong.
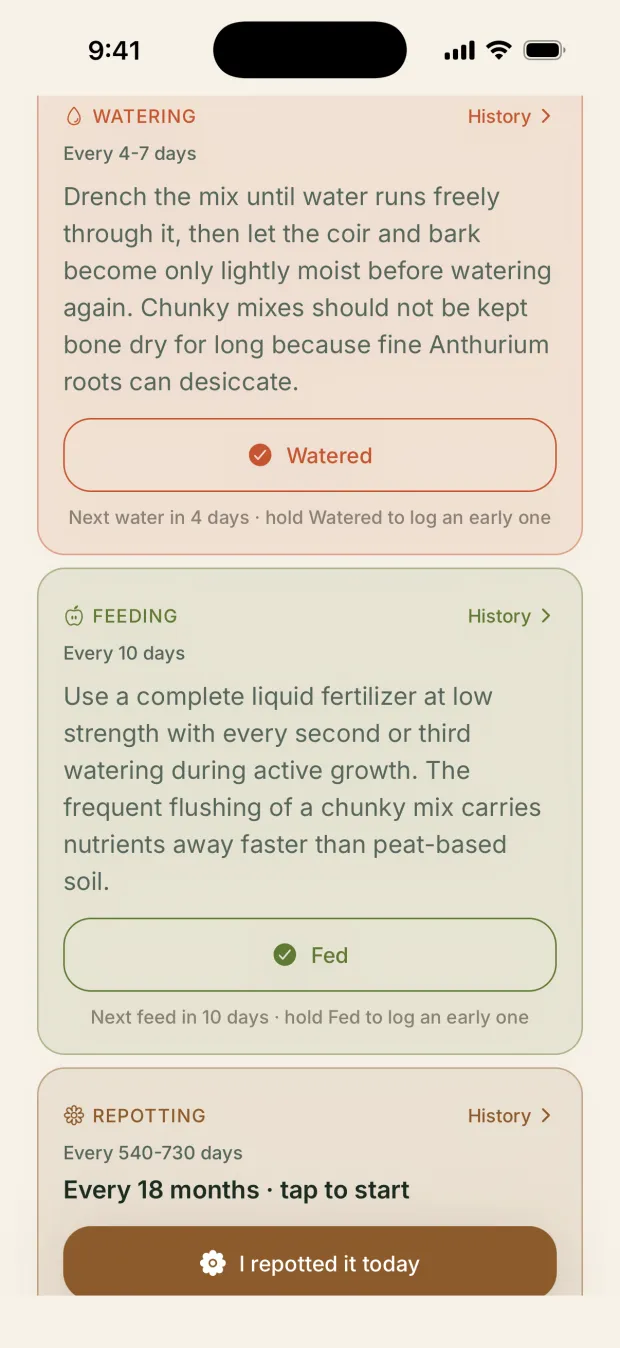
Care
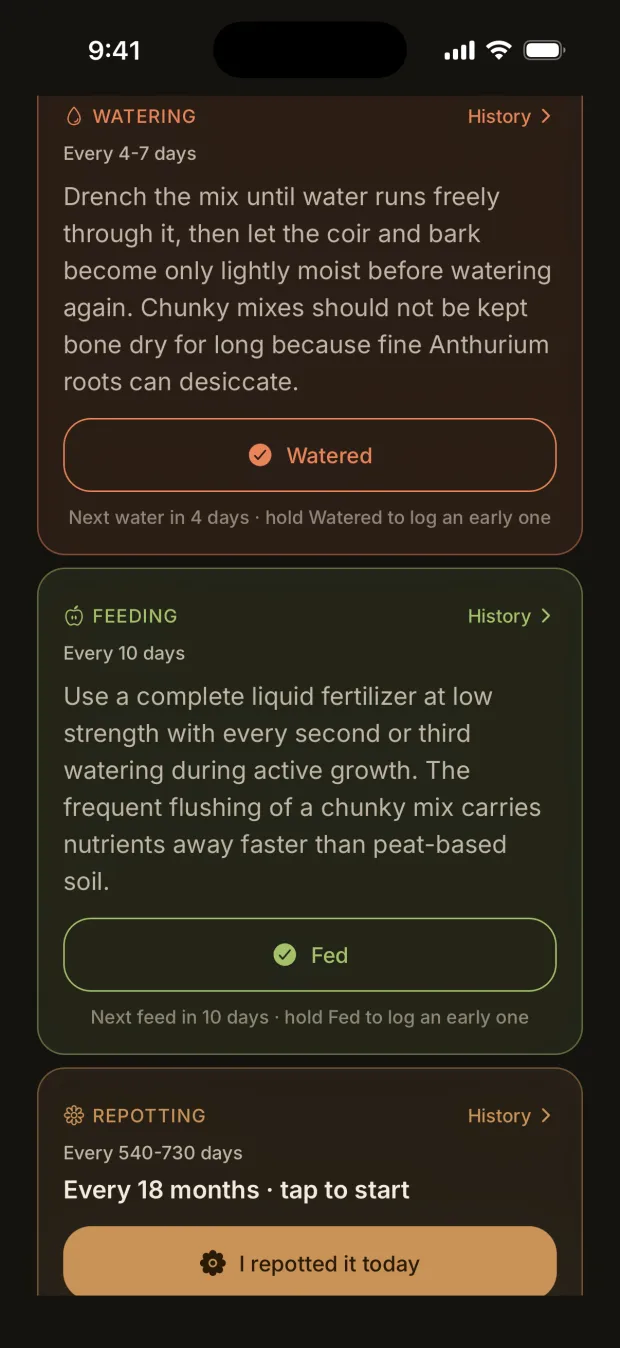
A schedule per plant, written for the medium it grows in.
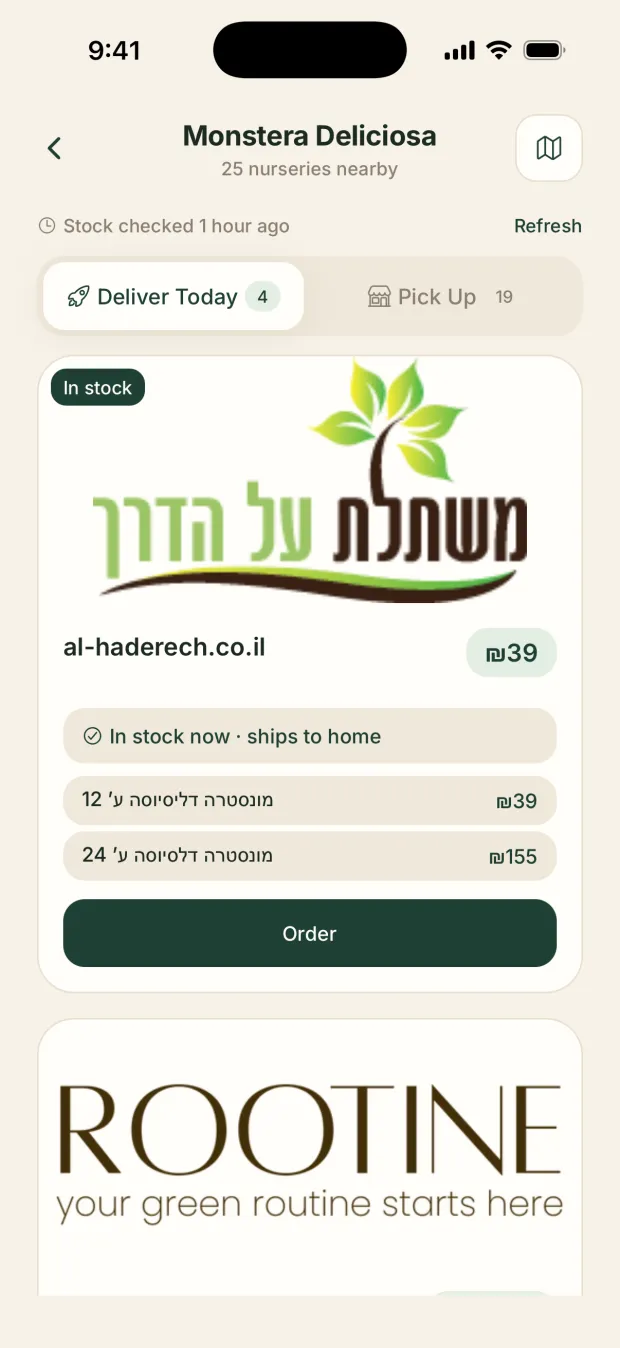
Find
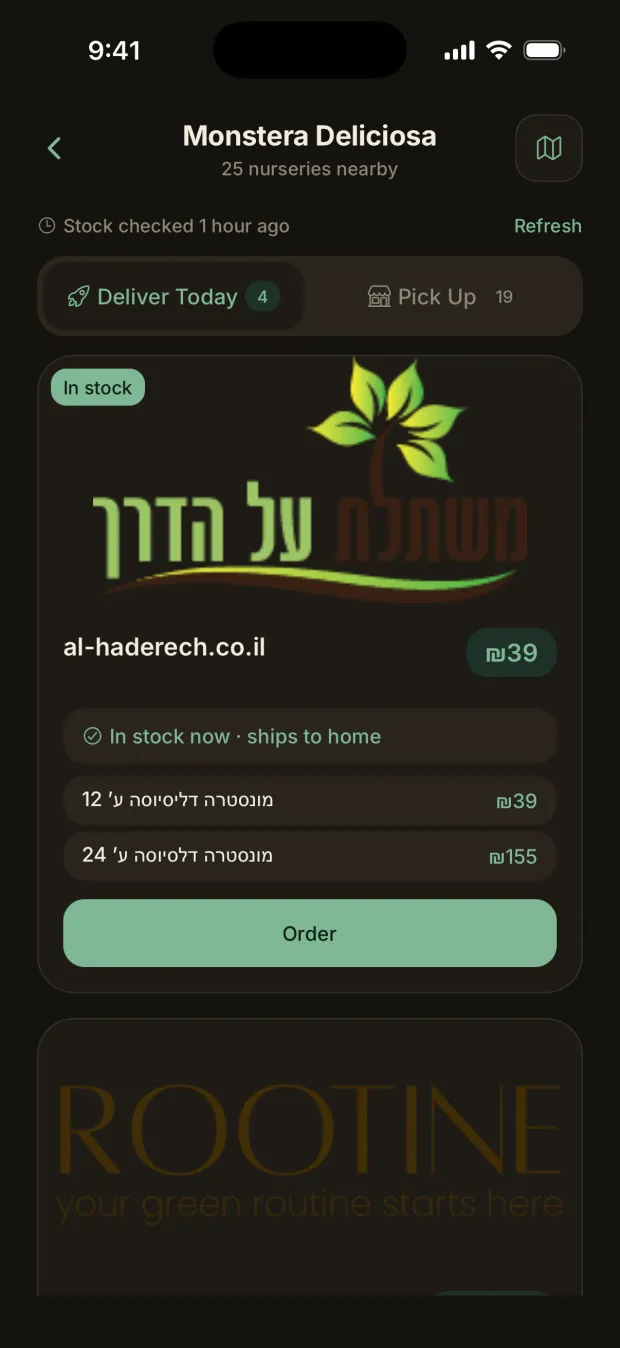
Live prices from Israeli nurseries that deliver.
What it does
Photograph a houseplant and PlantAI names the species, reads how it is doing, and writes a care plan for the pot it is actually growing in. Every plant lands in a library that follows the account rather than the handset, with watering reminders, one calendar for water, food, repotting and new leaves, and a photo journal. When a plant needs something you do not own - a fertiliser, an insecticidal soap, the plant itself - the app searches real Israeli nurseries for it and compares what they charge.
How it works
One photo, one gated API
The photo is resized on the device and posted to a Node API that holds every provider key. Requests carry a shared header and are metered - a per-minute limit per IP and a daily cap for the whole service - so the app ships with no AI or scraping key of its own.
Identify with a specialist first
PlantNet returns ten candidates and their scores are summed per genus, which is the level the care advice is actually written at. A 404 or an empty result means the photo is not a plant: the API answers 422 and the app says so, rather than diagnosing a coffee mug.
Ask the general model only when the specialist is unsure
GPT is called when PlantNet fails, scores under 40, or knows the genus but not the species - and its answer is only taken above 70. Most photos never reach it.
Say how sure it is
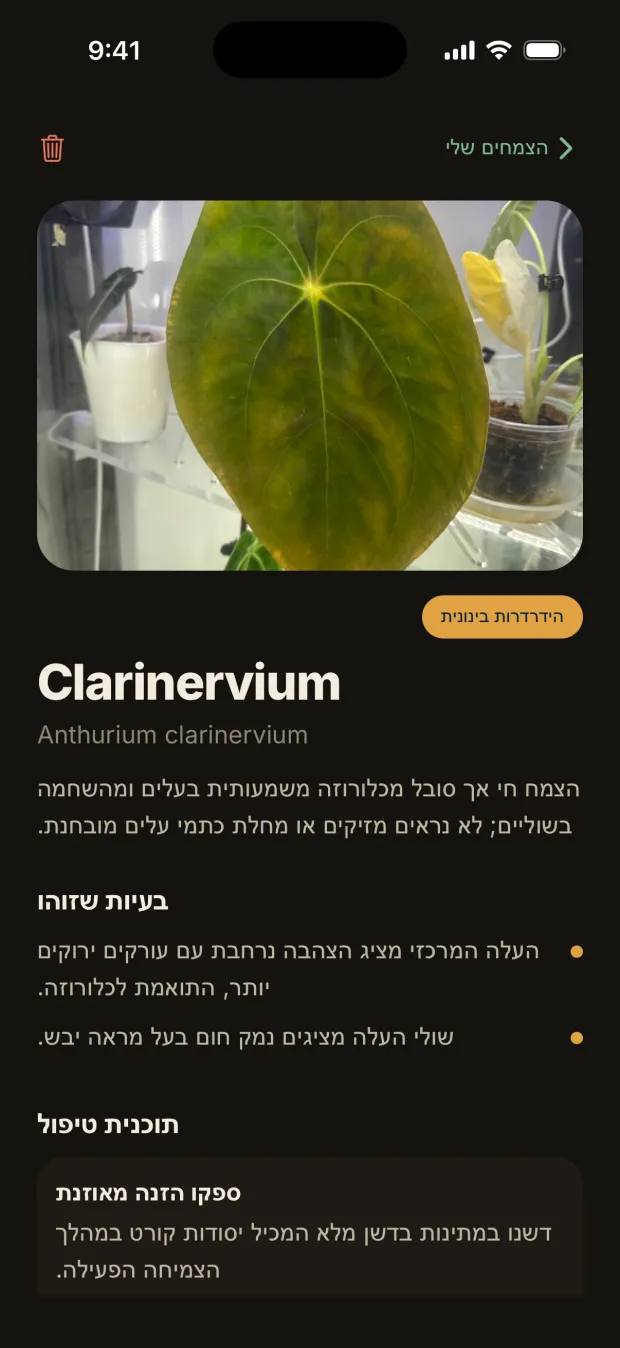
Confidence resolves to a tier - high, moderate, low, or genus-only - and the screen shows it. A 47% match opens with 'we are not certain of the species' and a retake button, because everything below that line assumes the identification was right.
Diagnose, then write the plan for the pot
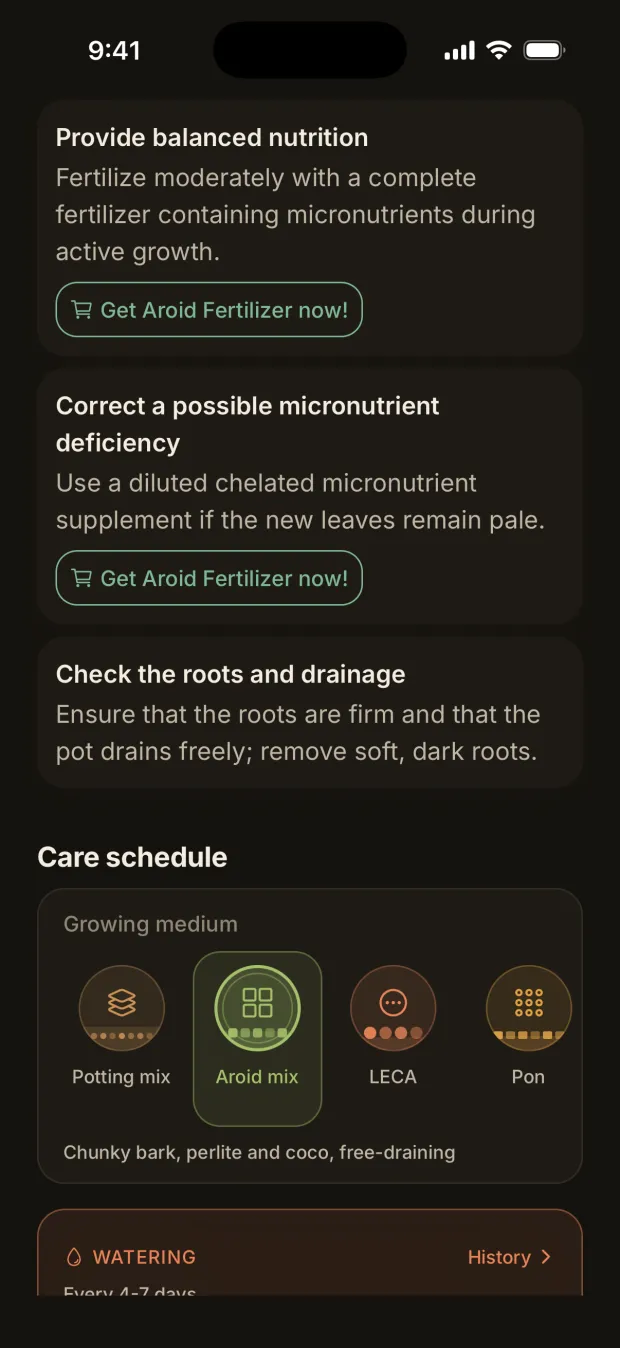
The same model reads the photo for health and produces the issues and treatments. The care plan is per genus and per growing medium, so potting mix, aroid mix, LECA and pon each get their own watering and feeding advice, cached per genus.
The library is the account
Supabase holds the account, the plants, their logs and their photos in a private bucket. Photos are mirrored to disk on the device, so a cold start paints the library instantly instead of waiting on the network.
The nursery search is a job, not a request
Reading real shops takes far longer than an HTTP request should, so the API answers with a job id and the app polls it - 1.5 seconds, backing off to 5. Identical searches merge into one job, and a cached search returns without spending the daily cap.
Read the shop, not the search engine
Each nursery site is fingerprinted as Shopify, WooCommerce, Wix, VirtueMart or unknown, then read through its own storefront API where it has one, and through Firecrawl, Tavily or its sitemap where it does not. A model plans the query, extracts the prices and verifies them; a shop that cannot be read says 'could not check this shop' instead of guessing.
The shape of it
Photo
resized on the device
- POST /api/diagnose:
Node API
gated, keys live here
- identify:
PlantNet
ten candidates, summed per genus
GPT
only when PlantNet is unsure
- health + plan:
GPT
per genus, per growing medium
- save:
Supabase
account, plants, photos
- separately, to act on it:
Google Places
nurseries nearby
- fingerprint each shop:
Shopify / Woo / Wix
storefront API where there is one
- otherwise:
Firecrawl
Tavily
and the sitemap, as fallbacks
- extract, then check:
GPT to JSON
Verify pass
or it reports it could not check
Tech choices
The decisions that shaped it, and why they went that way.
- A specialist model first, a general one only when it hesitates
- PlantNet is built for this one job and beats a general model at it. Chaining them the other way round - general model first - made both answers worse, so GPT is the fallback rather than the front door, and its answer is only trusted above a threshold.
- Uncertainty is a screen, not a log line
- A wrong species makes every sentence after it wrong, so the confidence tier is rendered: the percentage, a plain warning, and a retake button. Hiding a 47% match behind a confident-looking headline would be the most damaging thing this app could do.
- No provider key reaches the phone
- The app talks to one API and nothing else, so the keys for PlantNet, OpenAI, Places, Firecrawl and Tavily exist only on the server. The gate can run in log mode first, which matters because enforcing before the shipped builds carry the header locks every install out of its own API.
- The scraper is graded, not trusted
- Retrieval and price extraction are scored offline against captured pages and hand-written labels, never against the scraper's own output. The set that matters most is the quiet one - 133 pages where the right answer is 'this shop does not have it' and a false positive would put a wrong price in front of someone.
- Hebrew is a build, not a translation layer
- Every string lives in one of two copy files, the layout is really right-to-left rather than a mirrored English one, and an existing diagnosis is translated by the API on demand rather than being re-generated in the other language.
- Dead code fails the build
- Unused imports, locals and parameters are type errors, and both projects - the app and the server - are typechecked. CI runs the typecheck, both test suites and a Docker build on every pull request with no secrets at all, so a fork's PR runs the whole thing.
Built with
- Mobile
- Expo SDK 56React Native 0.85React NavigationReanimatedexpo-sqlitereact-native-maps
- API
- Node 26TypeScriptDockerRender
- Data
- Supabase PostgresAuthStorage
- AI & search
- PlantNetOpenAIGoogle PlacesFirecrawlTavily
- Quality
- GitHub Actionsnode:testJestRNTL
Inside the app
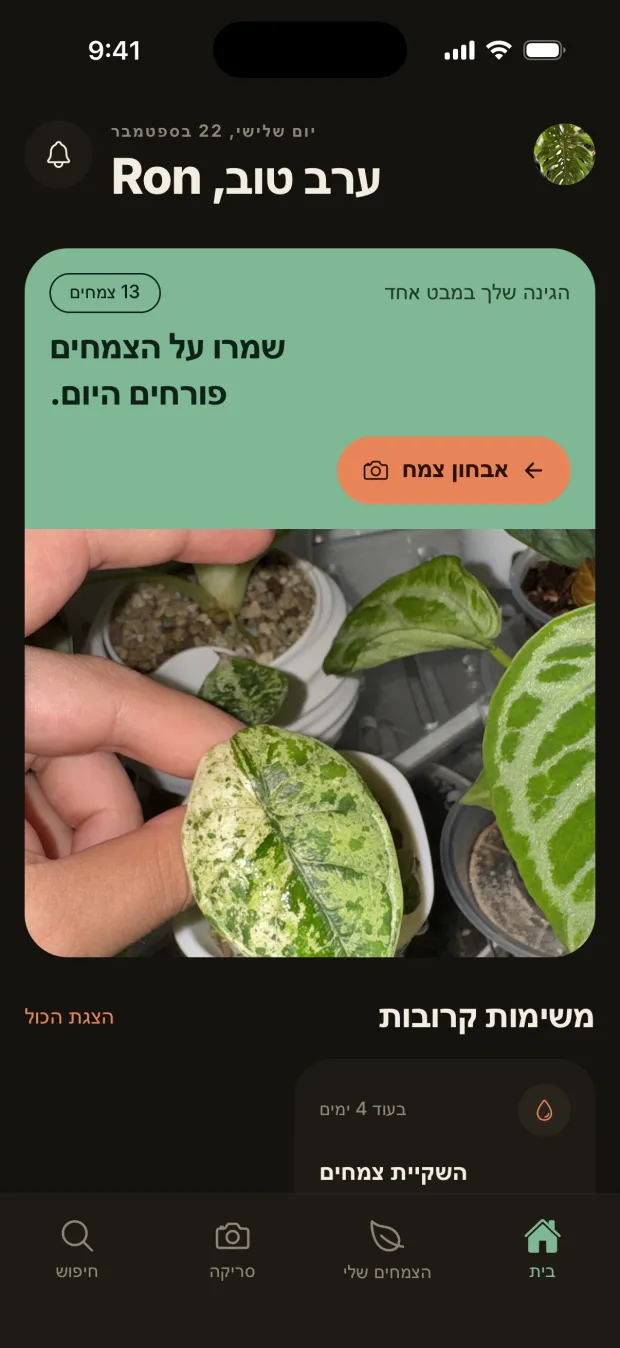
Captured on a phone against the live service. Scroll sideways for the rest.
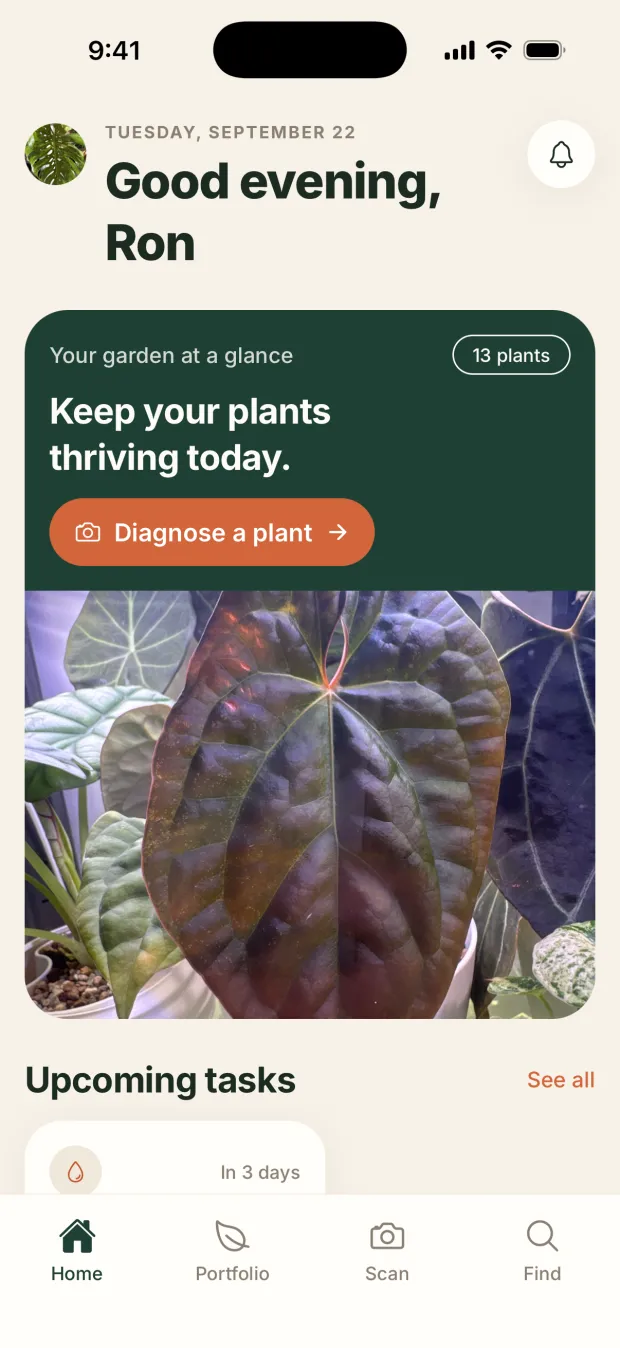
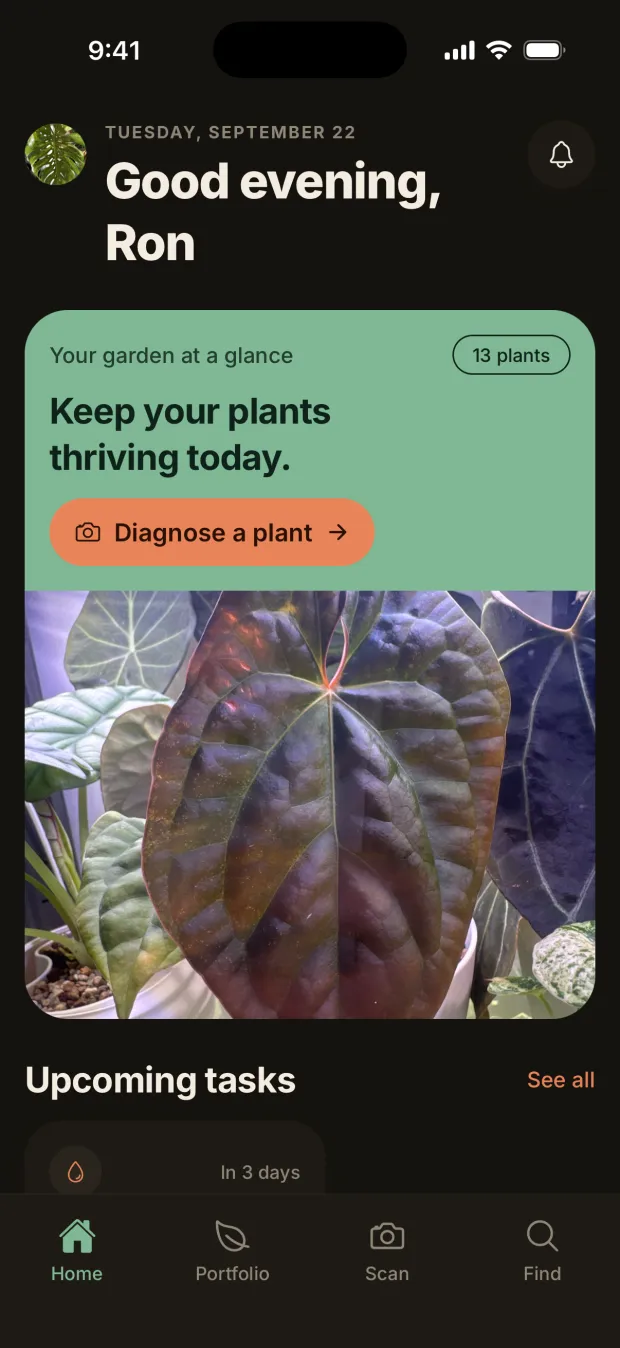
Today
The greeting, the garden at a glance, and what is due.
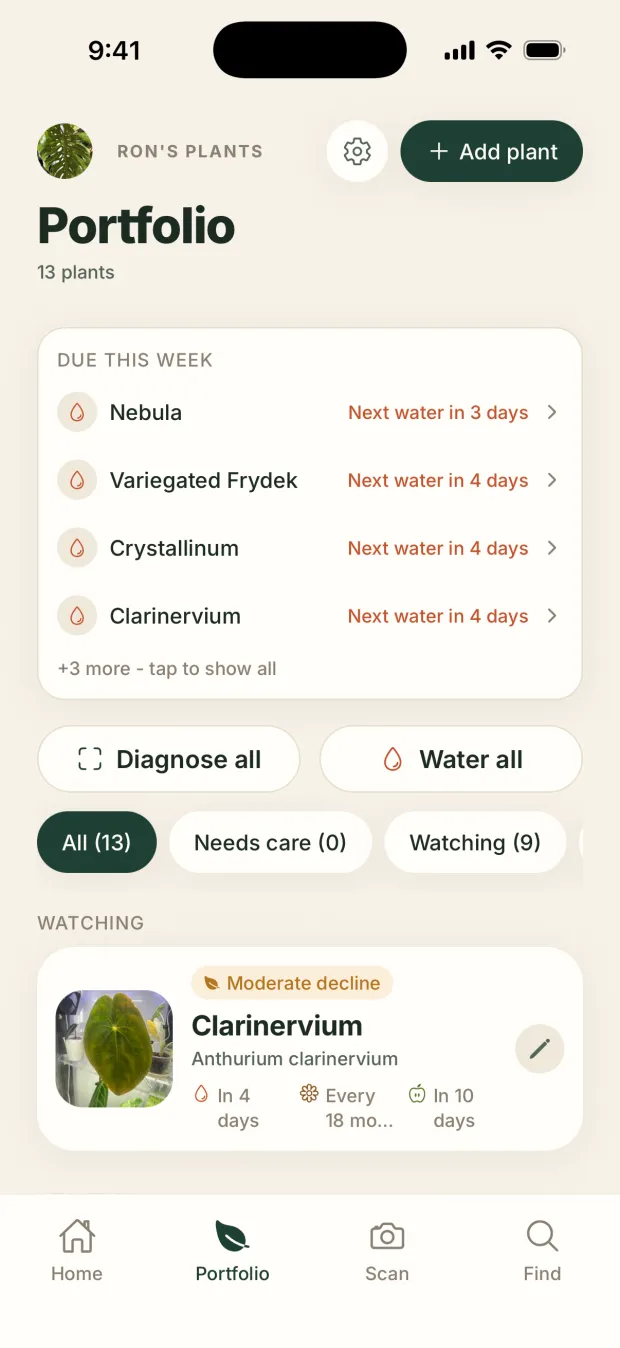
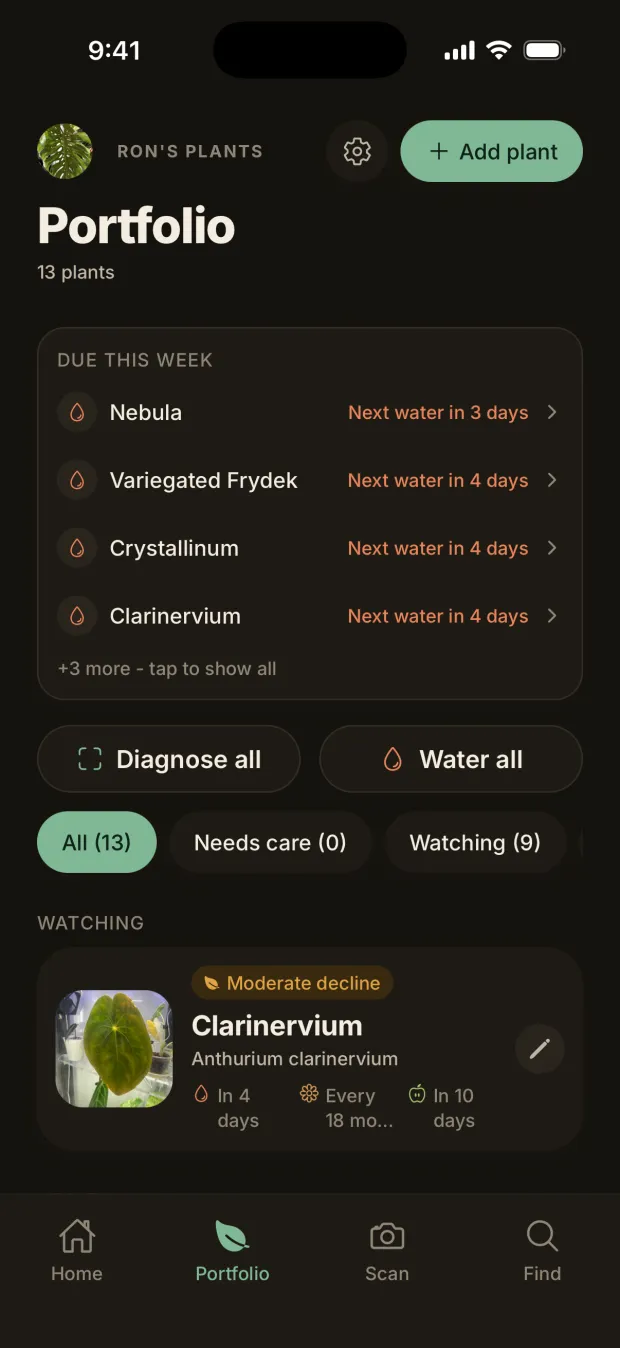
Library
Every plant, what it needs this week, and bulk actions.
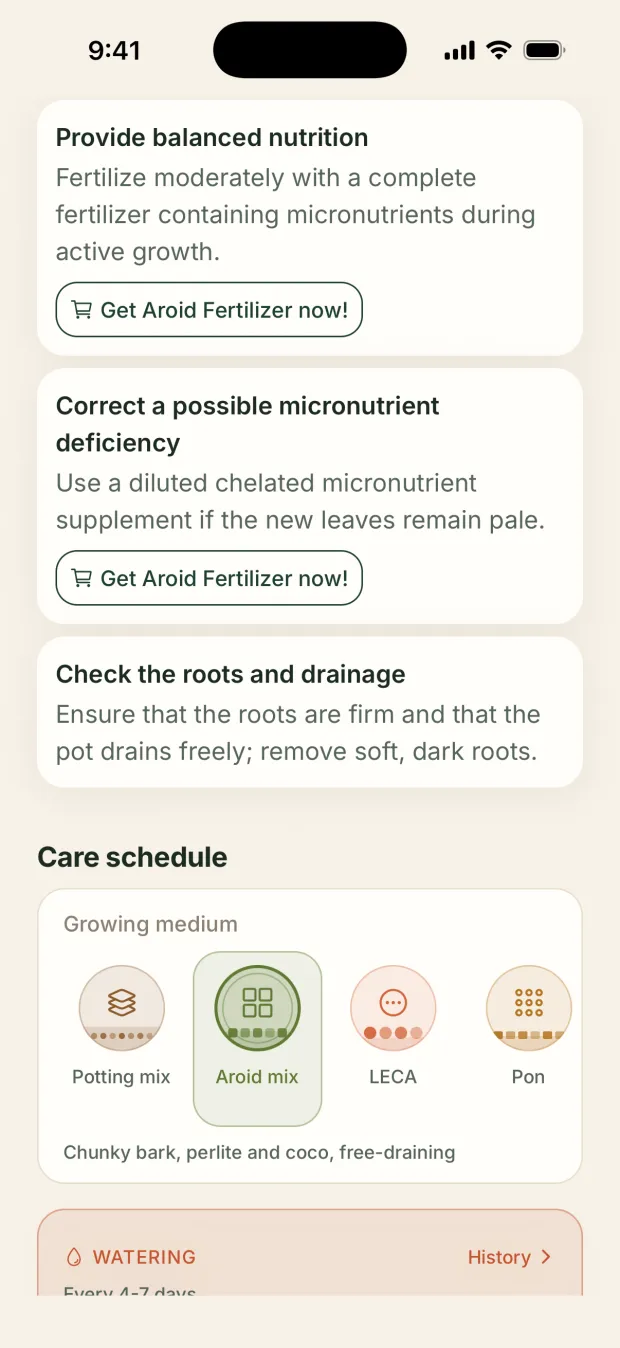
Treatment
Each step, and a shortcut to buy what it needs.
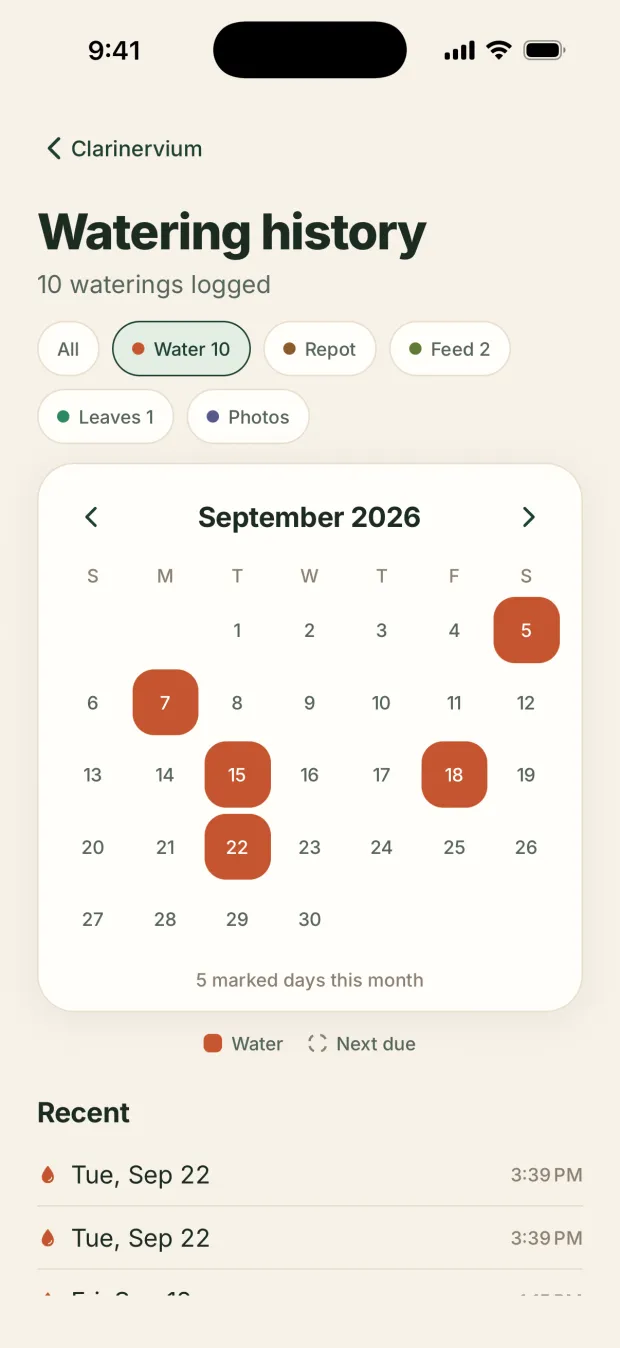
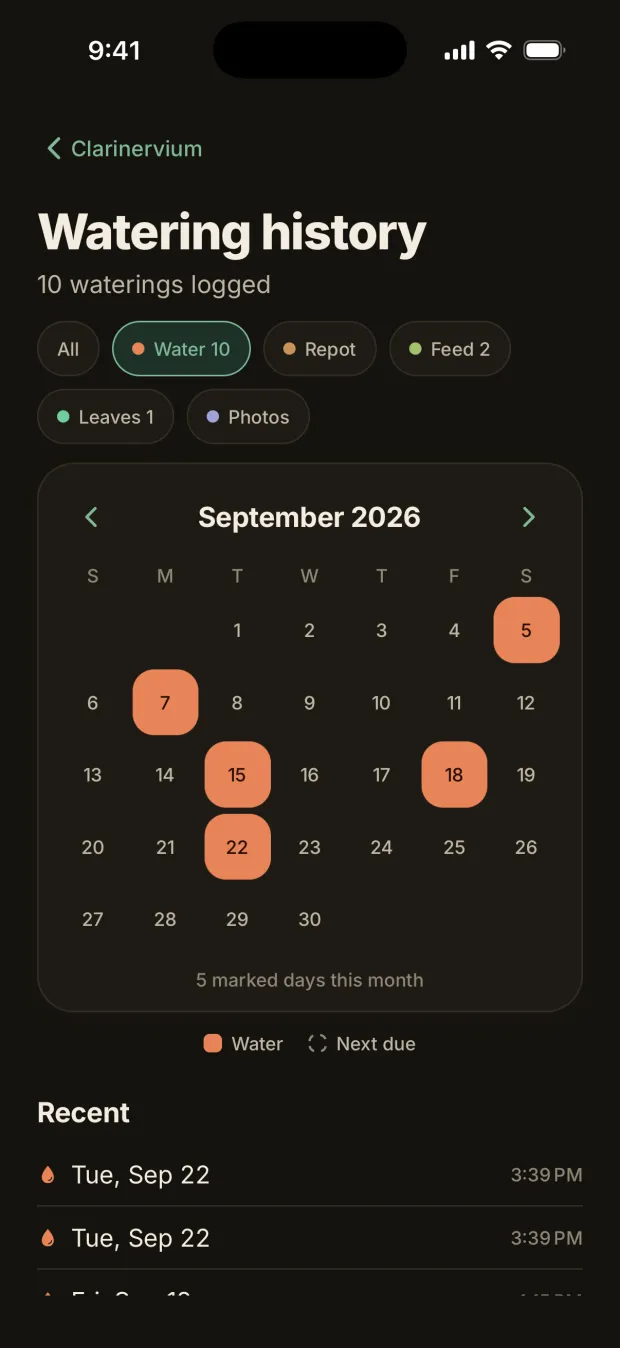
History
Water, food, repotting, leaves and photos on one calendar.
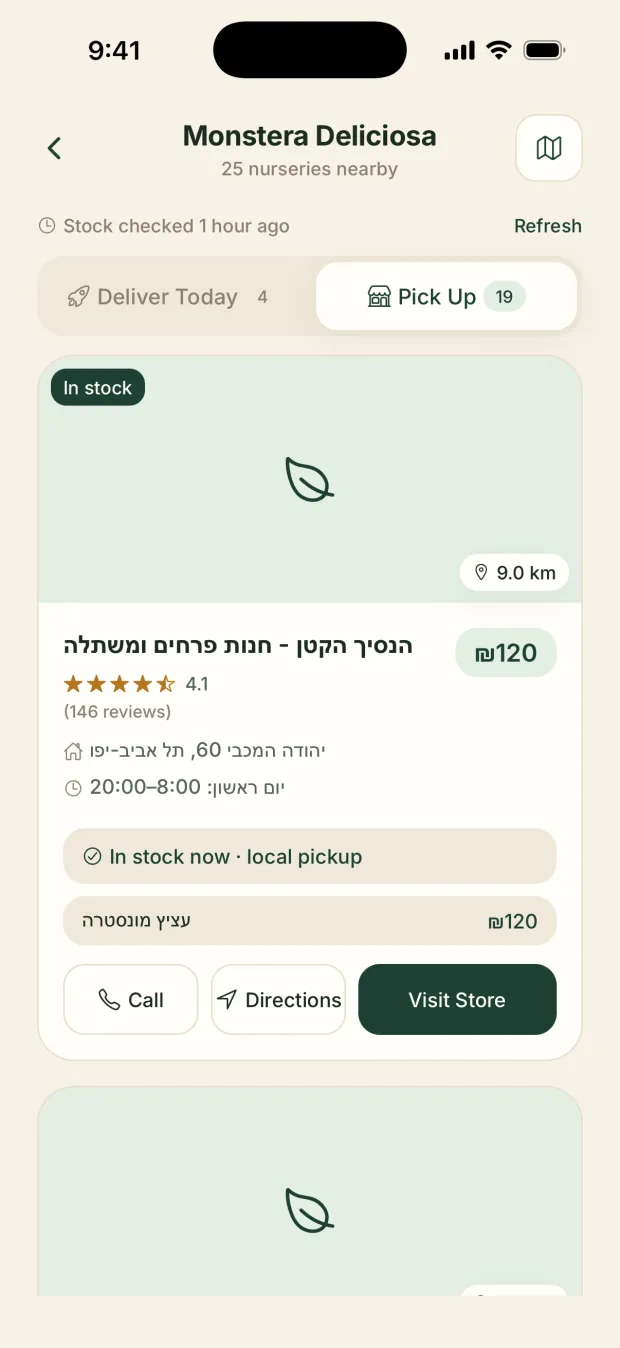
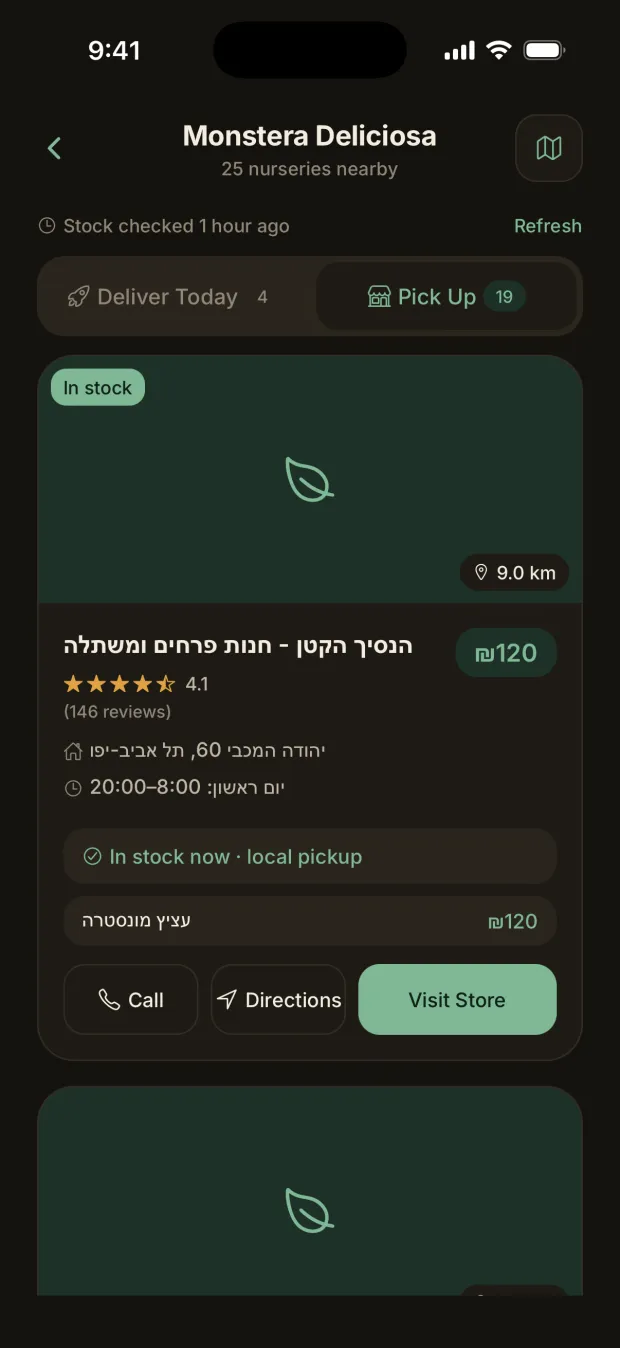
Pick up
Nurseries nearby, with distance, hours and stock.
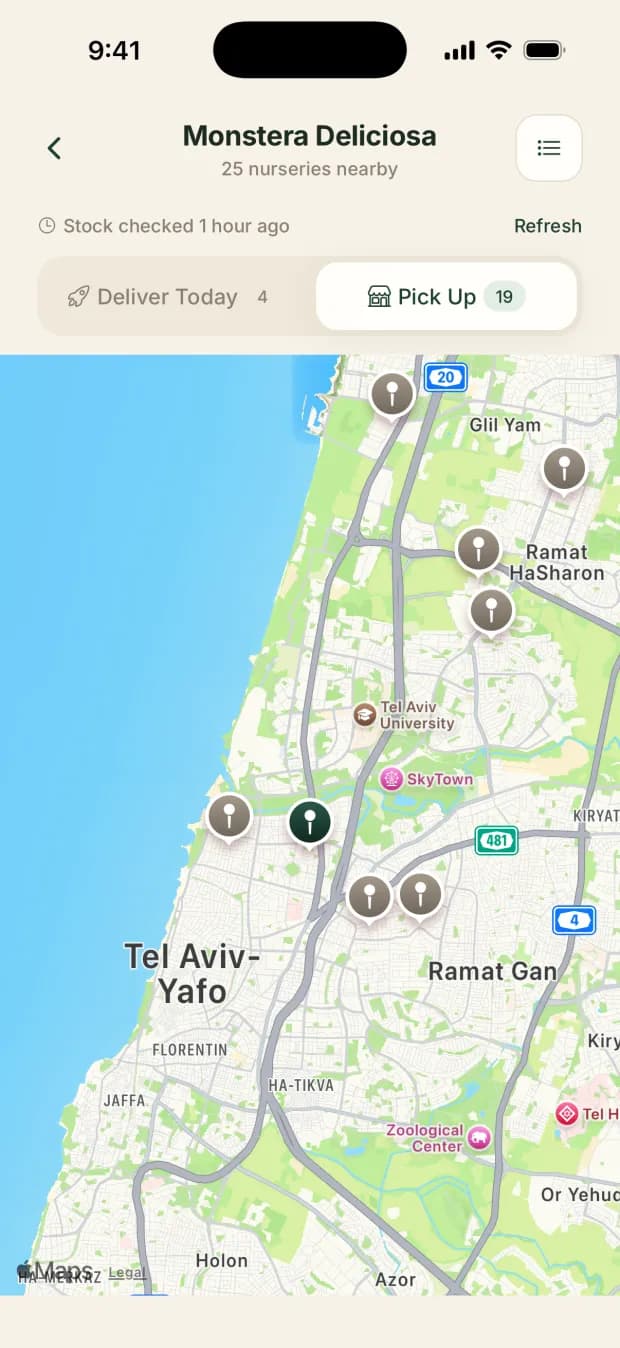
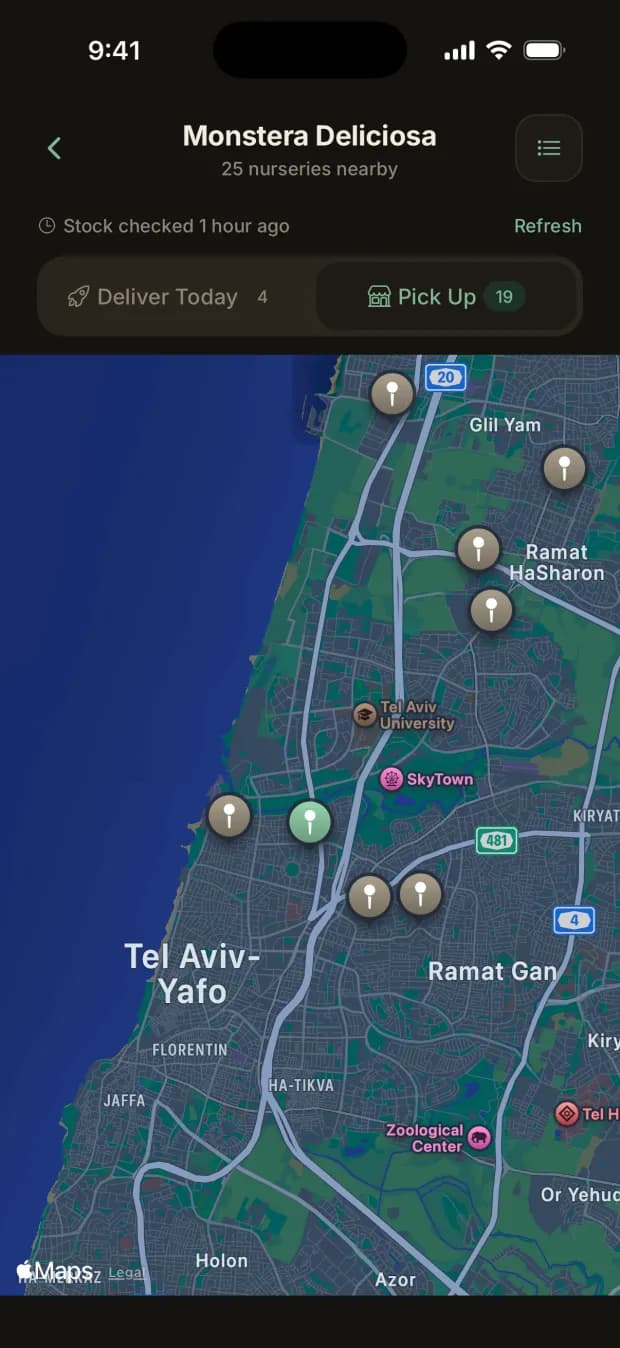
Map
The same results as pins, around where you are.
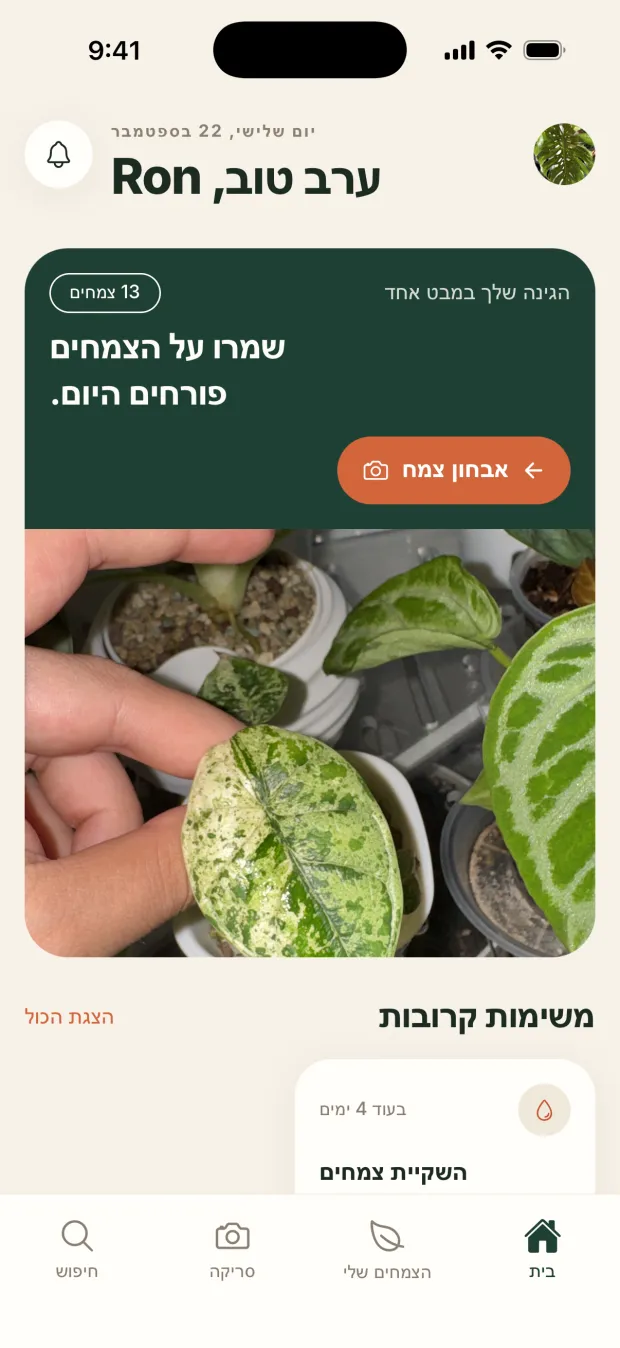
עברית
The Hebrew build is genuinely right-to-left.
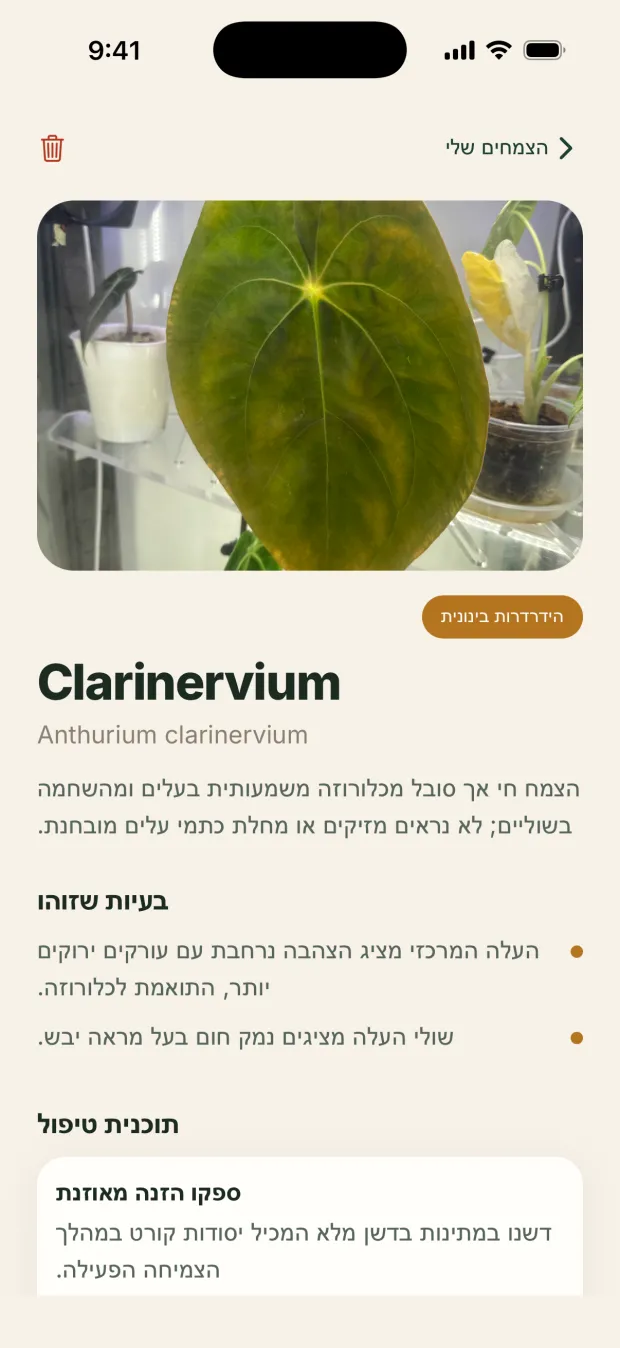
Translated
The same diagnosis, translated by the API on demand.
What it produces
How the repo is laid out
Roughly the order you'd read it in: entry point first, then the parts doing the work.
App.tsxExpo entry and the navigation stacksrc/screens/scan, diagnosis, plants, nurseries, accountsrc/lib/pure logic, a test beside every modulesrc/services/the stateful edges: plants, auth, mediaserver/the API: diagnose, care plans, gate, jobsscraper/nursery search: fingerprint, retrieve, pricescripts/offline scoring against labelled fixturessupabase/migrations/schema applied to the live projectdocs/api-site/the published API documentation site
Where it falls short
It is a proof of concept, not a product. It runs from Expo builds on my own phone and on the simulator, it is on neither store, and it has never had a user besides me. A diagnosis is a model reading one photo: the app shows how sure it is and says when it is not, but it can still be confidently wrong, and every treatment below that line assumes the species was right. The nursery search is the weakest part - reading live shops takes 30 to 90 seconds, some shops refuse the server's datacentre address and answer only from a home connection, so a shop that works when I test locally can fail in production. And the growth journal is still device-only: the plants, their photos and their logs follow the account, the journal does not.